Why mibz2 stops scaling at eight threads, and why three teams help
Each block decoded at once slows the others, and more threads per block barely help, so three teams of three beat four of two by 9%. Why blocks interfere is open.
On a ten-core desktop processor, mibz2, our bzip2 decoder written in Rust, got faster as we gave it more threads, from one to eight. Past eight it stopped. Twelve, sixteen or twenty threads decoded no faster than eight. A decoder that can't use the cores it is given leaves time on the table for anyone decompressing large files, and the reason it stops says where the next gain has to come from.
The reason is not the number of threads. It is how many pieces of the file the decoder works on at the same time. A bzip2 file is a series of blocks that can be decoded independently, and mibz2 decodes several at once, each with a small group of threads. We measured two things. Every extra block in progress slows down every other block. And extra threads on the same block barely speed it up. Together they mean that fewer blocks, each with more threads, beat more blocks with fewer threads. Our latest release, 0.2.5, decodes three blocks at once with three threads each, where 0.2.4 decoded four with two each. In two runs at ten threads, it was 8.8% and 8.9% faster, used 11–12% less processor time and 18–19% less peak memory.
What we have not measured is why the blocks slow each other down. The leading explanation is that each block needs a large table, and the tables compete for the processor's shared cache. The evidence for that comes from a simpler test program, not from the decoder itself, and a careful review of an earlier draft of this analysis made us withdraw part of it. So this post keeps three things apart: what was measured, what is inferred, and what we will test next.
Section 1 explains how mibz2 splits a file among its threads. Section 2 gives the measurements behind the two findings, and sections 3 and 4 look at each one in turn. Section 5 is the release's own measurement, section 6 what the review changed, and section 7 the next experiments.
1. How does mibz2 decode with several threads?
bzip2 compresses a file in blocks of up to 900 kB each (at its default level, 9). Each block is compressed on its own, with no reference to the others, so each can be decoded on its own too. That is what makes a parallel decoder possible: different threads can work on different blocks at the same time, and the decoder puts their outputs back in order at the end.
Decoding one block undoes bzip2's steps in reverse. One thread, which mibz2 calls the scanner, reads the compressed file and undoes its outermost layer, the Huffman coding, for every block (an earlier post covers that stage). The rest of a block's work happens on the threads that decode it, in three parts:
- MTF: undoing the move-to-front coding, which turns the scanner's symbols back into the block's bytes, though not yet in their original order.
- The inverse BWT: undoing the Burrows–Wheeler transform, which bzip2 used to reorder the bytes so that similar ones sit together. This puts them back in their original order.
- RLE1 and the CRC: expanding the runs of repeated bytes that bzip2 shortened first of all, and checking the result against the block's checksum.
The inverse BWT is the most expensive of the three. It works in two phases. The build makes a table with one 4-byte entry for each byte of the block, saying where the next byte of the original text is to be found. For a full block that table, which mibz2 calls the T-vector, is 3.6 MB. The walk then follows the table from entry to entry, writing out a byte at each step. Each step's address comes from the entry just read, so the steps form a chain through the table, jumping to an unpredictable place each time. A jump that finds its entry in a nearby cache is quick. One that has to go to main memory waits hundreds of cycles. Revisiting the space–time tradeoff in BWT inversion shows the transform and its table worked through on a small example.
A chain of dependent jumps can't be split between threads directly, since each step needs the one before. mibz2 gets around this by starting many chains at known points through the block, so several threads can share one block's build and walk. We call the threads that share a block a team. One of them, the leader, also does the block's MTF, RLE1 and CRC alone, and puts the walk's pieces together at the end (the assembly). The others are its helpers: they join in only for the build and the walk. A team decodes one block at a time, with one table, and then takes the next.
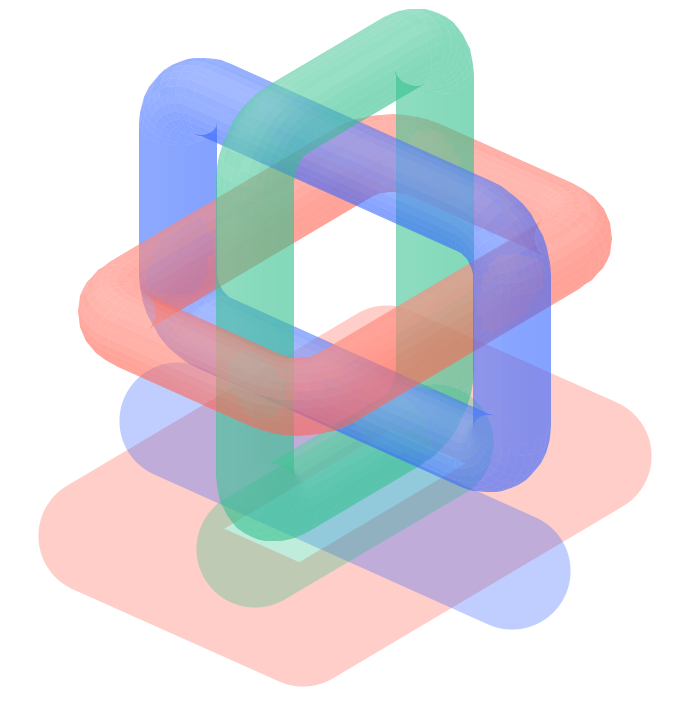
So a thread count is really two numbers: how many teams, which is the number of blocks and tables in progress at once, and how many threads each team has. We write a plan as teams × threads per team: 4 × 2 is four teams of two.
The machine these measurements come from is an Intel Core i9-10900K. It has 10 cores, each able to run two threads at once (20 in all), and a 20 MiB last-level cache, the L3, which all ten cores share. Until 0.2.5, mibz2's rule was teams of two, and as many teams as keep their tables within about 0.7 of the L3. On the test machine that is four teams. Asked for 8, 10, 12, 16 or 20 threads, the decoder ran the same four teams of two, plus the scanner. That is why it stopped at eight: past eight it declined the extra threads. Under that rule, 0.2.4 levelled off at about 1.27–1.31 GB/s of output from 8 threads up.
The two plans on the test machine's ten cores
2. What happens when we change the number of blocks, and the threads on each?
To see what four teams of two were missing, we ran a grid of plans that varied the two numbers separately: 2 to 8 teams, of 2, 3 or 4 threads each. Each plan decoded the same sample of the Wikidata dump, 11.85 MB of bzip2 that decodes to 209.7 MB, 20 times, in rotating order, with threads placed by the operating system as users run it. The figure below groups the plans by their number of teams. That is the most tables the plan can have in progress at once, not a measured count of how many were in progress at each moment.
Throughput by the number of teams, all thread counts per team together
Two things stand out. Each team gets slower as teams are added, and steeply: from 558–583 MB/s each with two teams, to 461–466 with three, about 320 with four and 110 with eight. Adding a fourth team adds a fourth block in progress, but makes every block slow enough that all four together are slower than three. Total throughput peaks at three teams, 1,382–1,399 MB/s.
And at a fixed number of teams, the threads per team hardly matter. With four teams, each team decoded 319, 325 and 320 MB/s with two, three and four threads. The extra threads cost processor time without buying speed. The table below gives the four-team plans against the old default, with the best three-team plans for comparison. "Against 4 × 2" is the ratio of throughputs, paired round by round, with its 95% interval across the 20 rounds; "CPU" is total processor time over 4 × 2's.
| plan | threads | MB/s | against 4 × 2 | CPU | peak memory, MB |
|---|---|---|---|---|---|
| 4 × 2 (the old default) | 8 | 1,276 | 1 | 1 | 82 |
| 4 × 3 | 12 | 1,300 | 1.017 (1.008–1.026) | 1.26 | 82 |
| 4 × 4 | 16 | 1,279 | 1.003 (0.993–1.014) | 1.52 | 82 |
| 3 × 3 | 9 | 1,382 | 1.075 (1.058–1.093) | 0.89 | 67 |
| 3 × 4 | 12 | 1,399 | 1.097 (1.083–1.111) | 1.04 | 68 |
The four-team rows were the experiment's registered tests: their pass rule, a gain of at least 3%, was fixed before any run. Neither passed. The three-team rows were exploratory: picked out after the fact, so they proved nothing on their own. They were then confirmed in runs registered for them, and the release's plan in two more (section 5). Peak memory, meanwhile, rose by about 15 MB with each team: 52 MB at two teams, 67 at three, 82 at four and 138 at eight.
That leaves two questions. Why does each extra block slow the others? And why doesn't a block go faster with more threads?
3. Why would more blocks at once slow each block down?
This part is inferred, not measured in the decoder. The leading explanation is about the shared cache. Each team's walk jumps unpredictably through its own 3.6 MB table, and is fast only while the entries it needs are in the L3. All teams share that one cache, so each extra table takes room the others were using. As an intuition: several people each searching their own large reference book, all spread out on one desk. With two books, most pages stay open. With eight, pages keep being put away to make room, and fetching them back is slow.
The evidence comes from a test program that runs only the inverse BWT, the build and the walk, with each block's thread fixed to a core of its own, and no teams. In October we ran it on the test machine with hardware counters, which count events inside the processor. One of them is the L3 hit share: of the memory requests that miss the cores' own small caches, the share the L3 answers rather than main memory. Plotted against the table bytes in use at once, it stays near 1 while the tables are small, then falls once they approach the cache's size.
L3 hit share against the table bytes in use at once (inversion only)
Four other observations from that program point the same way:
- Requests wait longer. A request that misses the cores' own caches waited on average 67 cycles with four tables, 137 with six and 361 with eight.
- Main memory saturates. From six tables on, traffic to main memory levels off at 28–29 GB/s.
- A control isolates the table's size. A variant that changes the walk's code but keeps a 4-byte table got the same hit share as the standard one at six tables (0.814 against 0.793).
- A smaller table moves the drop. A 3-byte table (2.7 MB a block) moved the program's best number of blocks from four to six, where it ran 1.100 (1.093–1.108) times as fast as the standard table's best.
That is good evidence that the size of the tables matters, in that program. It doesn't settle the question for the decoder, for three reasons.
First, the program isn't the decoder. It has no teams, no MTF, RLE1 or CRC, no scanner, and none of the decoder's other buffers. Second, table bytes don't explain everything even there. With the smaller level-3 blocks, ten tables kept a hit share of 0.940 and yet ran slower than eight, mostly in the build, with requests waiting longer at nearly the same hit share. So a limit on how many requests the cores can have outstanding, or on the number of cores loading the cache at once, is not ruled out. Third, the decoder's own counters were never read: the operating system's settings on the test machine didn't allow it during the team-size run.
There is also a simpler puzzle. Four full tables are 14.4 MB, below the cache's 20 MiB. Each team has other buffers besides its table, such as space for the walk's pieces and for the block's output: several megabytes of reserved capacity each. But capacity is not what is being read at any moment, and how much of those buffers sits in the cache at once is not measured. An earlier draft of this analysis added those capacities up to a 20 MiB "hot set" that filled the cache. The review showed that a sum of capacities and peaks can't establish that, and the claim was withdrawn (section 6).
Two other explanations also fit the measurements. The teams' waits for each other could be what makes blocks slow, rather than memory. And three teams of three use nine threads on ten cores, so one core is free, which changes how the operating system schedules everything else. No measurement of the decoder yet tells these apart.
4. Why don't more threads on one block help?
Measured: with four teams, a third thread per team bought 1.7% (0.8–2.6%) for 26% more processor time, and a fourth bought nothing detectable, 0.3% (−0.7% to 1.4%), for 52% more. A trace of each block's decode, which records when each block starts and finishes, shows the same thing from inside: with four teams, a block took on average 1.394, 1.380 and 1.403 ms with two, three and four threads.
Part of the reason is plain arithmetic: not all of a block's work is shared. Only the build and the walk are, and only inside the call that does the inverse BWT. The leader does the MTF before that call, and RLE1 and the CRC after it, alone.
One block's work in a team
The traces give the time inside and outside the inversion call for each block:
| plan | a block's decode, ms | inside the inversion call, ms | outside it, ms | outside share |
|---|---|---|---|---|
| 4 × 2 | 1.394 | 0.993 | 0.400 | 28.75% |
| 4 × 3 | 1.380 | 0.935 | 0.441 | 32.14% |
| 4 × 4 | 1.404 | 0.946 | 0.462 | 32.64% |
These are averages over the sample's 431 blocks, some of them small, so they are not the time for one full 900 kB block. On one of the cloud machines that benchmark every change to mibz2 (CI), with one thread, the stages cost, per output byte: 0.41 ns for MTF, 0.04 for assembly, 0.05 for RLE1 and 0.07 for the CRC, which the leader does alone, against 0.48 for the build and 1.09 for the walk, which a team shares.
So about 29–33% of a block's time is outside the shared part, and more threads can't shorten it. But that share is not the whole of the work that can't be shared. The inversion call also includes work the leader does alone (setting up, and assembling the pieces), and time the team spends waiting for its slowest member. The time outside the call also includes scheduling and the tracing itself. The traces can't separate these, so the true unshared share isn't known.
What the measurements don't separate is why the shared part itself doesn't speed up with a third or fourth thread. The candidates, each visible in the code, are:
- the cost of waking helpers and of waiting for the last one to finish;
- the setup and assembly the leader does alone, inside the call;
- the build's checks that each thread writes only its own part of the table;
- the number of pieces a block is split into, which grows with the threads per team;
- two threads sharing one core, once there are more threads than cores;
- memory, as in section 3.
Waiting isn't free either: a helper with nothing to do checks for work up to 2,000 times before it sleeps, which costs processor time.
One more measurement bears on core sharing. With four teams pinned to particular processors, giving the threads one core each ("spread") against pairing them on cores ("packed") made the biggest difference at two threads a team: packed was 23% slower (1,055 against 1,369 MB/s in the median round). With three threads a team it was 8% slower, and with four, 1%. But the packed arm also had fewer cores to use (4 against 8 for eight threads), so this compares how many cores were available, not which threads shared them.
5. What did three teams of three gain?
The grid's three-team plans were chosen after the fact, so before changing the decoder we registered a test of the change itself, with its pass rule fixed before any run: 0.2.5's plan against 0.2.4's, at 8 to 20 threads, 20 rounds each, and a second run to confirm it. Both runs passed. At ten threads:
| run | speed against 0.2.4 | processor time | peak memory |
|---|---|---|---|
| first | 1.089 (1.075–1.103) | 0.88 | 0.82 |
| confirmation | 1.088 (1.076–1.101) | 0.89 | 0.81 |
The intervals are 95% intervals across the 20 paired rounds of one run. Neither run detected harm at 11, 12, 16 or 20 threads, the registered check there. A separate comparison of the two releases found 0.2.4 taking 11.9% longer than 0.2.5 at ten threads, and 8.1–8.7% longer at 12 to 20.
At ten threads or more on a machine of this shape (ten cores, a 20 MiB L3), 0.2.5 runs three teams of three. A request for twenty threads still decodes on nine. The result covers this processor and this workload. It shows that three teams are faster. It doesn't show why, which is section 3's open question.
6. What did the review change?
The first version of this analysis was reviewed adversarially by another member of the project, who recomputed its numbers from the archived traces. All seven objections were accepted, and the version this post is based on takes them in. Four changes matter for the argument.
The first draft claimed that the decoder's buffers formed a 20 MiB working set that filled the cache. That was a sum of reserved capacities and peaks, not a measurement of what is read at the same time, and it was withdrawn. The first draft also read the flat block times in section 4 as memory saturation. The review pointed out that they can't separate memory from waiting, unshared work or core sharing, and that claim was withdrawn too. The outside share in section 4 was also recomputed: the first draft divided by the wrong total, and called the whole inversion call "build and walk", when it includes setup, assembly and waits. And the first draft's 1.10–1.30× estimate for the next experiment was replaced by the model in section 7, which shows that no such floor follows from the measurements.
7. What will we try next?
First: let the leader work on other blocks while its helpers build and walk. Today a team's helpers wait while the leader runs MTF before a block and RLE1 and the CRC after it. In the proposed pipeline, the leader runs the next block's MTF and the previous block's RLE1 and CRC while the other threads build and walk the current one. It needs one more buffer for the next block's bytes, about 1 MB a team. A prototype is being built.
A team's timeline, today and as proposed
Whether it pays is not obvious, because the shared part loses a thread: in a team of three, the build and walk would run on two. A simple model, from the review, puts numbers on that. Let \(S\) be the leader's work outside the shared part, \(P_0\) the shared part today, \(\alpha\) how much slower the shared part runs with a thread fewer and more blocks in progress, and \(H\) the cost of hand-offs that can't overlap. Then the time a team spends per block, today and pipelined, and the speed-up, are
For three teams of three, the grid's throughput gives \(C_0\) = 1.056 ms a block per team: three teams, 209.7 MB in 431 blocks, at 1,382 MB/s. That figure includes start-up and the end of the run, so it is an approximation, not a measured service time. Taking \(S\) = 0.40 ms, the time outside the inversion call in section 4, leaves \(P_0\) = 0.656 ms. The model's speed-up then depends almost entirely on \(\alpha\):
Modelled speed-up of the pipeline, against α
If the shared part ran no slower, the pipeline would be 1.61× as fast, or 1.50× with 0.05 ms of hand-off cost per block. If it ran 40% slower, 1.15× or 1.09×. At 1.6× slower the gain is gone. If the shared part slowed to what it takes under four teams of two, 0.94–0.99 ms, the gain would be 1.07–1.12×, or 1.02–1.07× with the hand-off cost. Nothing measured so far says which \(\alpha\) to expect, so no gain and a loss are both possible outcomes, and will be registered as such.
The test will compare like with like. To isolate the pipeline, pipelined against not pipelined at the same plan and thread count: three teams of four against three teams of four, and three of three against three of three. Separately, pipelined three of four against today's default at ten threads, which is the comparison a user would care about. Each will report processor time and peak memory alongside the elapsed time. The prototype must also record when each thread starts and finishes each stage of each block, so that the trace shows blocks really overlapping. Without that, a result says nothing about the mechanism.
Second: placement, as a control. Pinned against unpinned threads, recording which thread ran on which processor, for today's plan and for three teams of four. It makes no prediction of its own. It is needed to read the pipeline's result, since that plan uses more threads than there are cores.
Third: a smaller table under teams. The inversion-only program's 3-byte table moved the fall in hit share to more blocks, so the table's size is a real factor. But that table's 1.10× gain was against the same program's standard table, not against the decoder: against the decoder's own team code (four teams of two), in the same tests, it ran at 0.687 (0.680–0.695) of the speed, on six cores against eight. A different compact table, which packs 30 entries into each 64-byte record, ran 4.8% and 7.7% slower than the standard one at four threads on CI. And no smaller table has been measured under teams. So it comes after the first two.
Last: shrinking the other buffers. There is no measurement of how much cache they take, so nothing yet says this would help.
8. Where do things stand?
The chain of the argument runs like this. A thread count is really two numbers, blocks in progress and threads per block. Each extra block slows every other block, enough that three blocks beat four. Extra threads on one block barely help, partly because about a third of a block's time is work its leader does alone. So three teams of three beat four teams of two, as two registered runs confirmed. Why extra blocks hurt is not settled: competition for the shared cache is the leading explanation, with good evidence from a simpler program and none yet from the decoder.
The pipeline prototype, its registration and the placement control are in progress. Nothing in this post changes the decoder.
The general lesson: more threads help only if the work they add runs alongside the slowest step. Here the slowest step has two parts, the blocks competing with each other, and each block's work that one thread does alone.
Research records:
- The analysis of the scaling limit, revised after review, and the review with its recomputation
- The team-size grid and traces
- The three-team policy: registration and both runs
- The release comparison, 0.2.4 against 0.2.5
- The smaller-table test with counters and the footprint journal
- The compact table under the staged walk
- The CI run with the stage costs